> For the complete documentation index, see [llms.txt](https://academy.pentaho.com/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://academy.pentaho.com/pentaho-data-integration/data-integration/data-sources/big-data.md).
# Big Data
{% hint style="info" %}
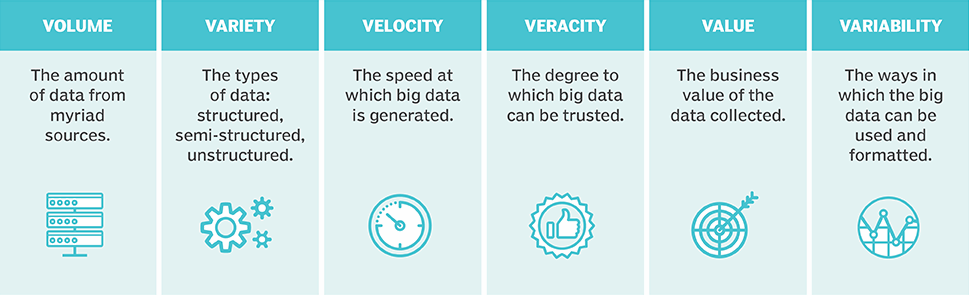
Big Data refers to extremely large and complex datasets that traditional data processing tools can't handle effectively. It's characterized by the "six Vs":
Think of social media posts, sensor readings, transaction records, and video files all being created simultaneously across millions of devices.
The challenge with Big Data isn't just storing these massive datasets, but extracting meaningful insights from them quickly enough to be useful. Organizations use specialized technologies like distributed computing systems (such as Hadoop and Spark) and cloud platforms to process and analyze this information. Machine learning algorithms help identify patterns that would be impossible for humans to spot manually.
Big Data has transformed how businesses operate and make decisions. Companies use it for everything from predicting customer behavior and optimizing supply chains to detecting fraud and personalizing recommendations. In healthcare, it helps analyze patient records and research data to improve treatments. The key value lies not in having lots of data, but in using advanced analytics to turn that data into actionable intelligence that drives better outcomes.
{% endhint %}
***
{% hint style="info" %}
**Workshops**
{% endhint %}
{% tabs %}
{% tab title="Apache Hadoop" %}
x
x
{% content-ref url="/pages/MeTNsXZW0WrnyqieOUKE" %}
[Apache Hadoop](/pentaho-data-integration/data-integration/data-sources/big-data/apache-hadoop.md)
{% endcontent-ref %}
{% endtab %}
{% tab title="Snowflake" %}
{% endtab %}
{% endtabs %}
x
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.
Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:
```
GET https://academy.pentaho.com/pentaho-data-integration/data-integration/data-sources/big-data.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.